How Maintenance Teams Trace Faults Through Server Racks
How Maintenance Teams Trace Faults Through Server Racks
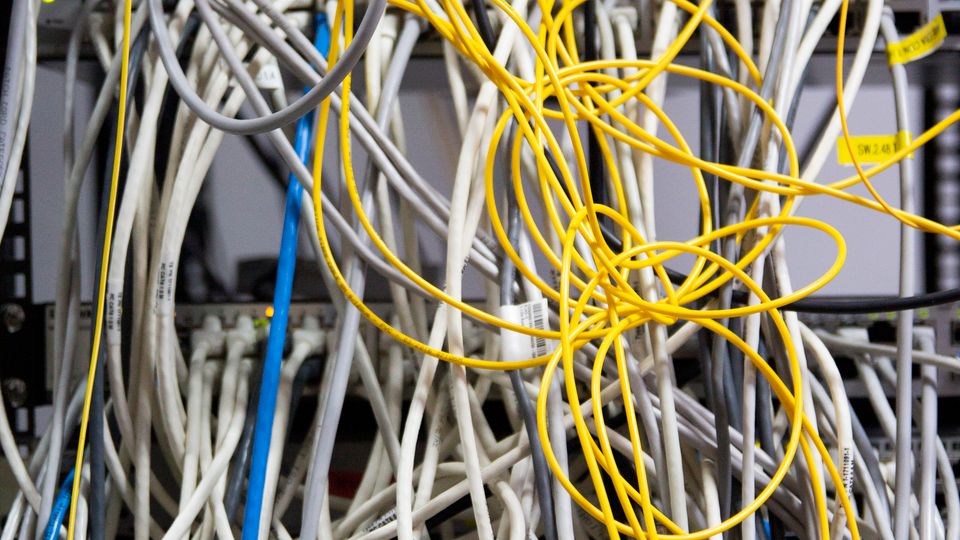
Clear labeling and repeatable checks reduce the time spent hunting through dense installations.
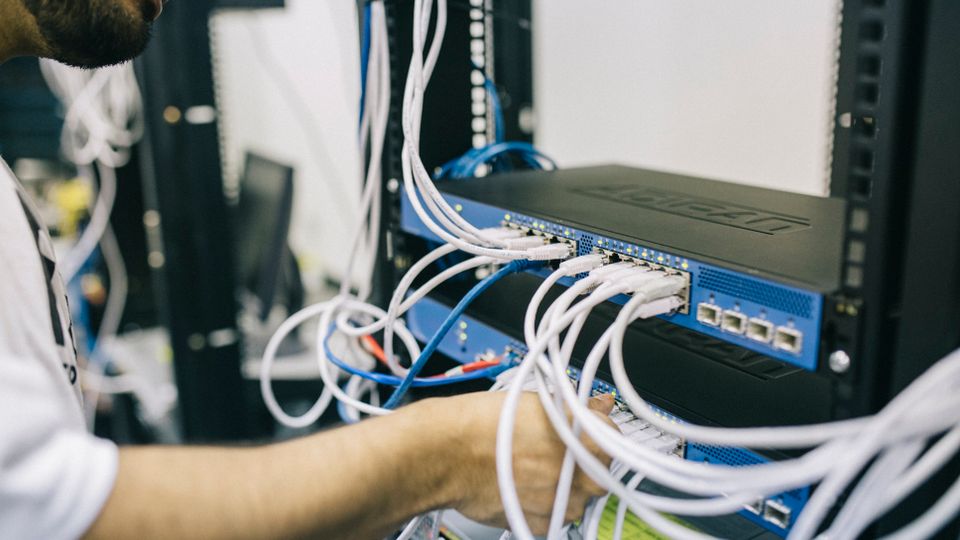
A rack fault may start with a cable, transceiver, power supply or upstream switch. Operators compare alarms across nearby devices to determine whether the problem is local or shared.
A recent patch change or power event can provide context, but the timeline matters. Some alarms appear only after the primary failure has already disrupted services.
Maintenance records should include the affected port, equipment identifiers and verification after replacement. The next technician can then distinguish a recurring fault from a new incident.